Publications
2026
Under embargo
Paper #1 with the DINO team at Meta
Title, authors and details will appear here once the work is public.
Under embargo
Paper #2 with the DINO team at Meta
Title, authors and details will appear here once the work is public.
-
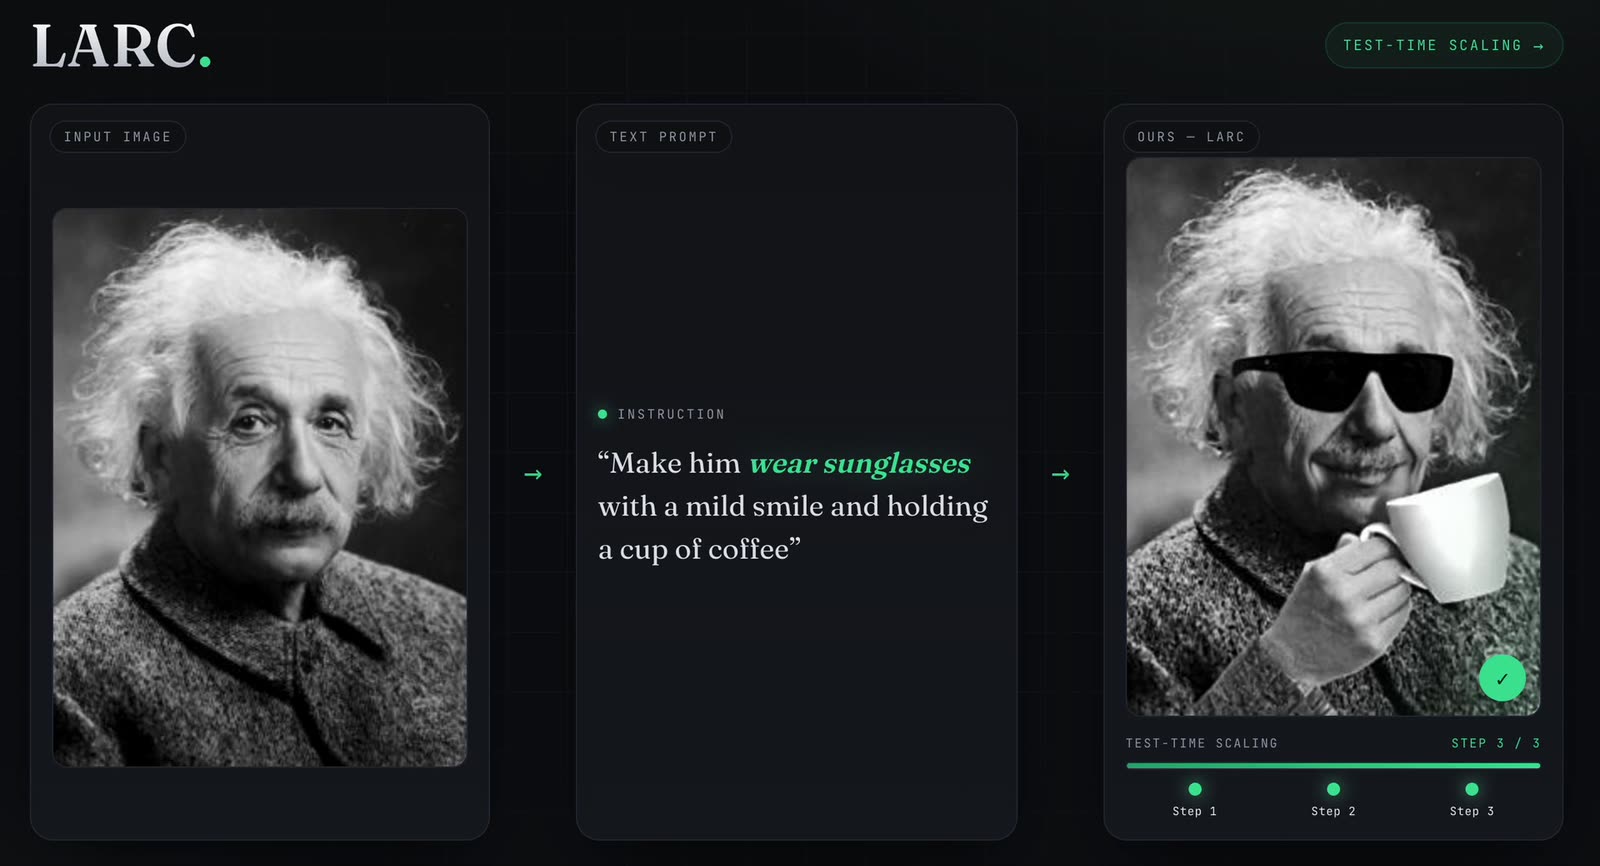
Multimodal LLMs & Generation
Lets image-generating multimodal models think in continuous latents, so more thinking gives better images.
LARC: Latent Reasoning in Continuous Space for Unified Multimodal Models
† Equal advising
- Multimodal LLM
- Generation
Problem
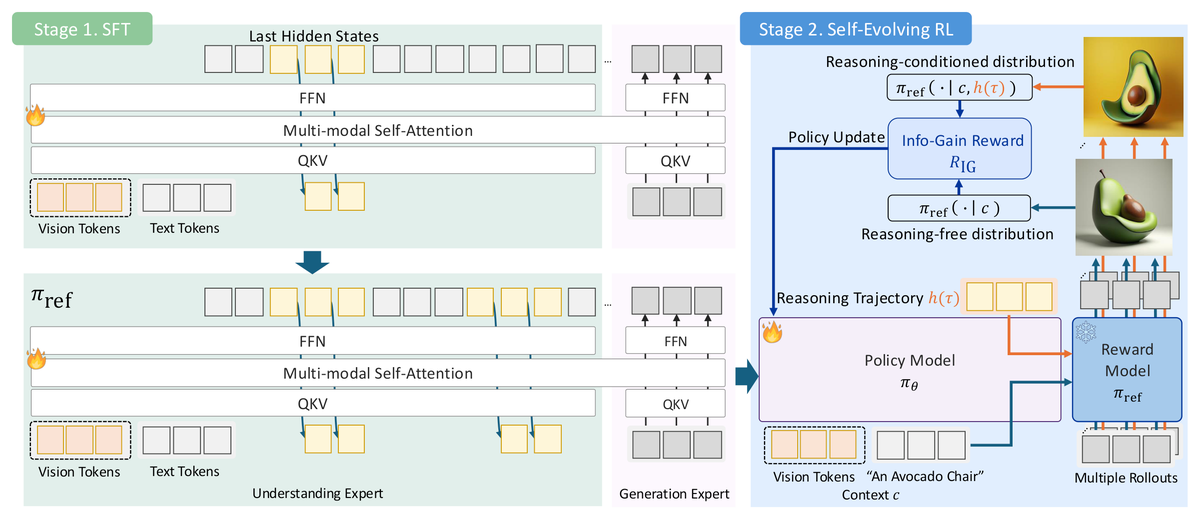
Unified multimodal models reason in discrete text tokens but draw images in a continuous space, so spending more on reasoning does not buy better images.
Key idea
LARC moves the reasoning into continuous space: the model interleaves short text spans with latent steps built from its own hidden states. Curriculum fine-tuning teaches latent reasoning, then self-evolving RL rewards each trace by how much it helps predict the target image.
Result
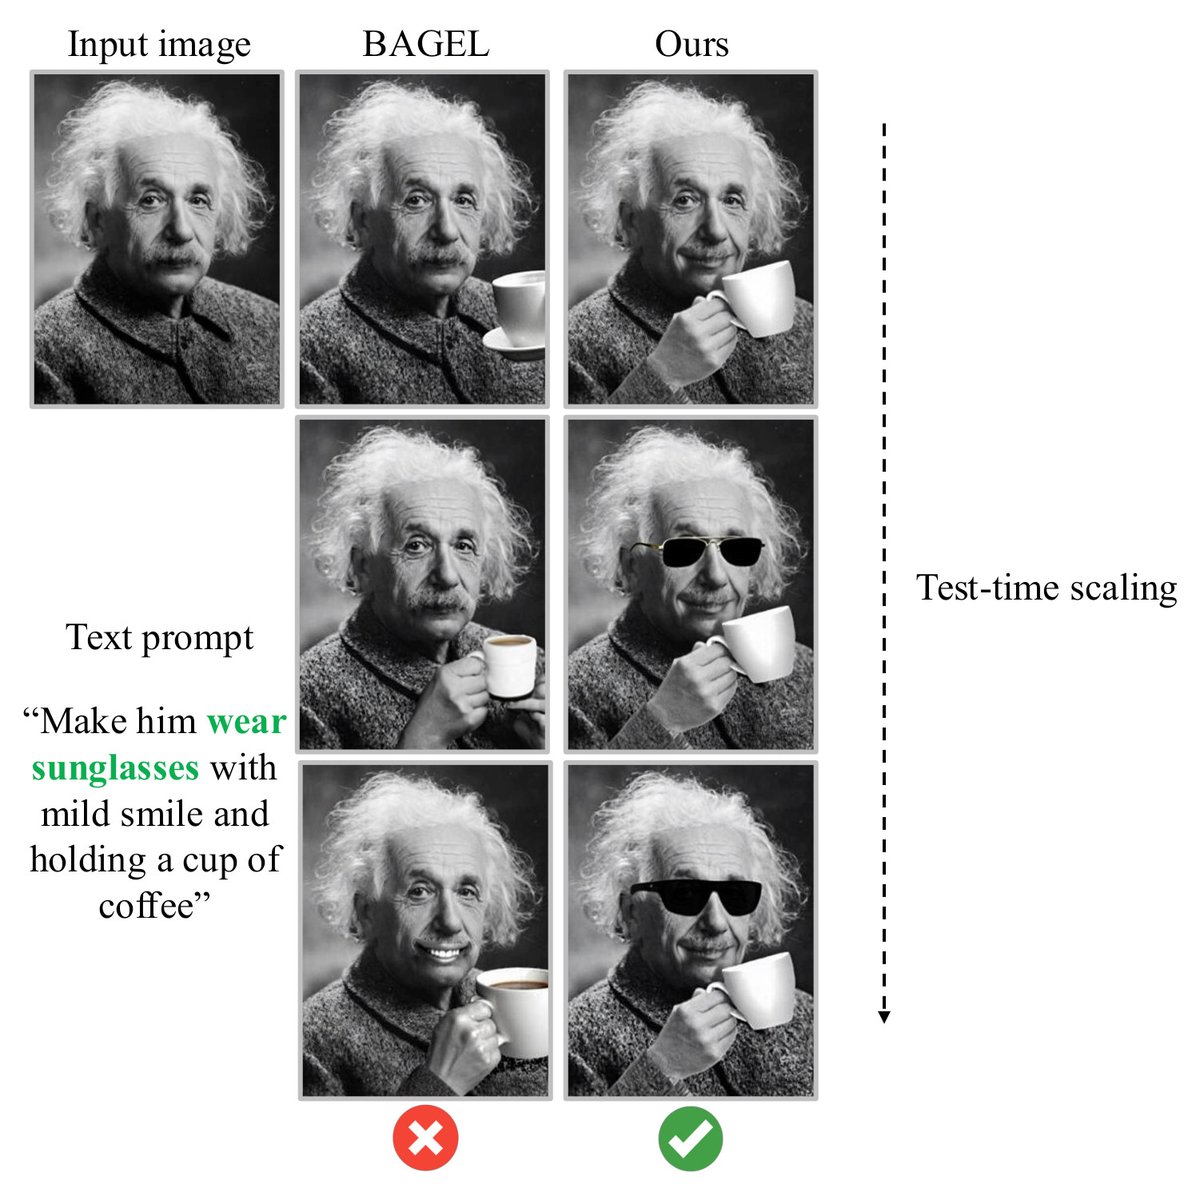
Beats its base model BAGEL and the token-reasoning Uni-CoT on text-to-image generation, image editing and visual reasoning, and shows clear test-time scaling: more latent steps, better images.
My role
Second author, on continuous latent reasoning that improves image generation in unified models.
BibTeX
@inproceedings{jeon2026larc, title = {LARC: Latent Reasoning in Continuous Space for Unified Multimodal Models}, author = {Jeon, Byungwoo and Jeong, Yoonwoo and Lee, Hyunseok and Cho, Minsu and Shin, Jinwoo}, booktitle = {Conference on Neural Information Processing Systems (NeurIPS)}, year = {2026}, } -

Multimodal LLMs & Generation
Keeps multimodal LLMs looking at the image while they think, so long reasoning stops washing out what they saw.
Vision-aligned Latent Reasoning for Multi-modal Large Language Model
† Equal advising
- Multimodal LLM
Problem
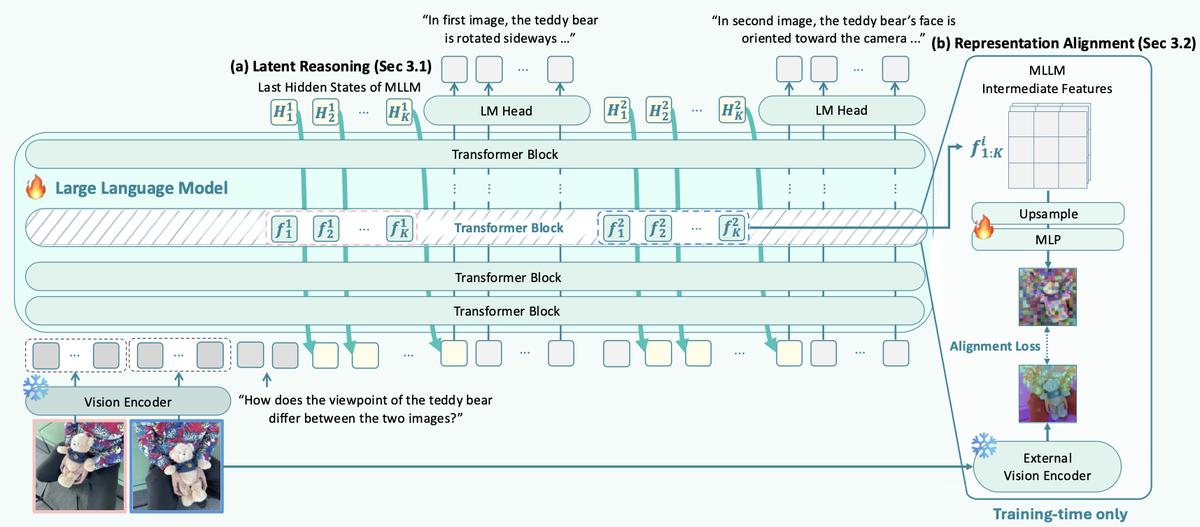
During long chains of thought, visual information gets progressively diluted, so multimodal LLMs struggle with multi-step reasoning and gain little from thinking longer.
Key idea
Before each reasoning step, VaLR generates latent tokens aligned with features from vision encoders such as DINOv3, keeping the reasoning grounded in perceptual cues.
Result
+19.9%p on VSI-Bench over Qwen2.5-VL (33.0% to 52.9%)
Raises VSI-Bench accuracy from 33.0% to 52.9% over Qwen2.5-VL, and keeps improving as reasoning gets longer.
My role
Second author, on injecting knowledge from vision foundation models into multi-view VLMs.
BibTeX
@inproceedings{jeon2026valr, title = {Vision-aligned Latent Reasoning for Multi-modal Large Language Model}, author = {Jeon, Byungwoo and Jeong, Yoonwoo and Lee, Hyunseok and Cho, Minsu and Shin, Jinwoo}, year = {2026}, eprint = {2602.04476}, booktitle = {International Conference on Machine Learning (ICML)}, archiveprefix = {arXiv}, } -

Multimodal LLMs & Generation
Gives multimodal LLMs an explicit 3D map of the scene, so they reason about space instead of guessing it.
Cog3DMap: Multi-View Vision-Language Reasoning with 3D Cognitive Maps
* Equal contribution
- Multimodal LLM
- 3D Understanding
Problem
Multimodal LLMs read multi-view images as mostly semantic tokens, so they must infer the 3D layout of a scene implicitly, and spatial questions suffer.
Key idea
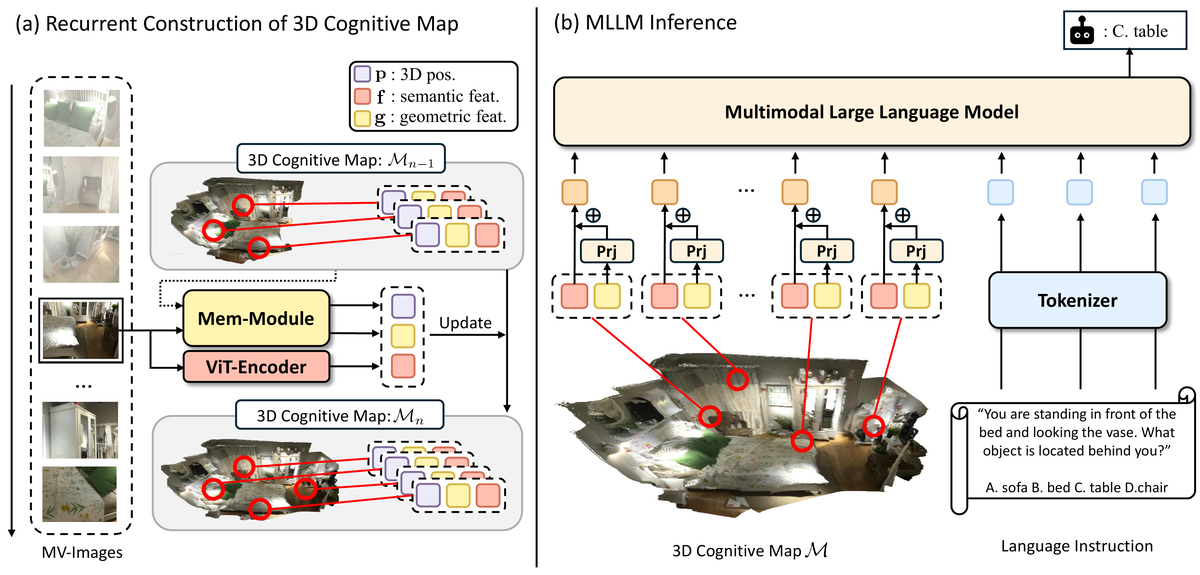
Cog3DMap recurrently builds an explicit 3D memory from the images: one token per spatial location, carrying both semantic and geometric features. The LLM then reasons directly over this compact map.
Result
+8.7%p on VSTI-Bench over the previous best
New state of the art on VSTI-Bench (+8.7%p over the previous best) and VSI-Bench (+3.9%p), while using up to 90.2% fewer visual tokens on long sequences.
My role
Co-first author (equal contribution) of this work on 3D cognitive maps that strengthen the 3D reasoning of VLMs.
BibTeX
@misc{gwak2026cog3dmap, title = {Cog3DMap: Multi-View Vision-Language Reasoning with 3D Cognitive Maps}, author = {Gwak, Chanyoung and Jeong, Yoonwoo and Jeon, Byungwoo and Lee, Hyunseok and Shin, Jinwoo and Cho, Minsu}, year = {2026}, booktitle = {arXiv preprint}, eprint = {2603.23023}, archiveprefix = {arXiv}, } -
3D Understanding & Segmentation
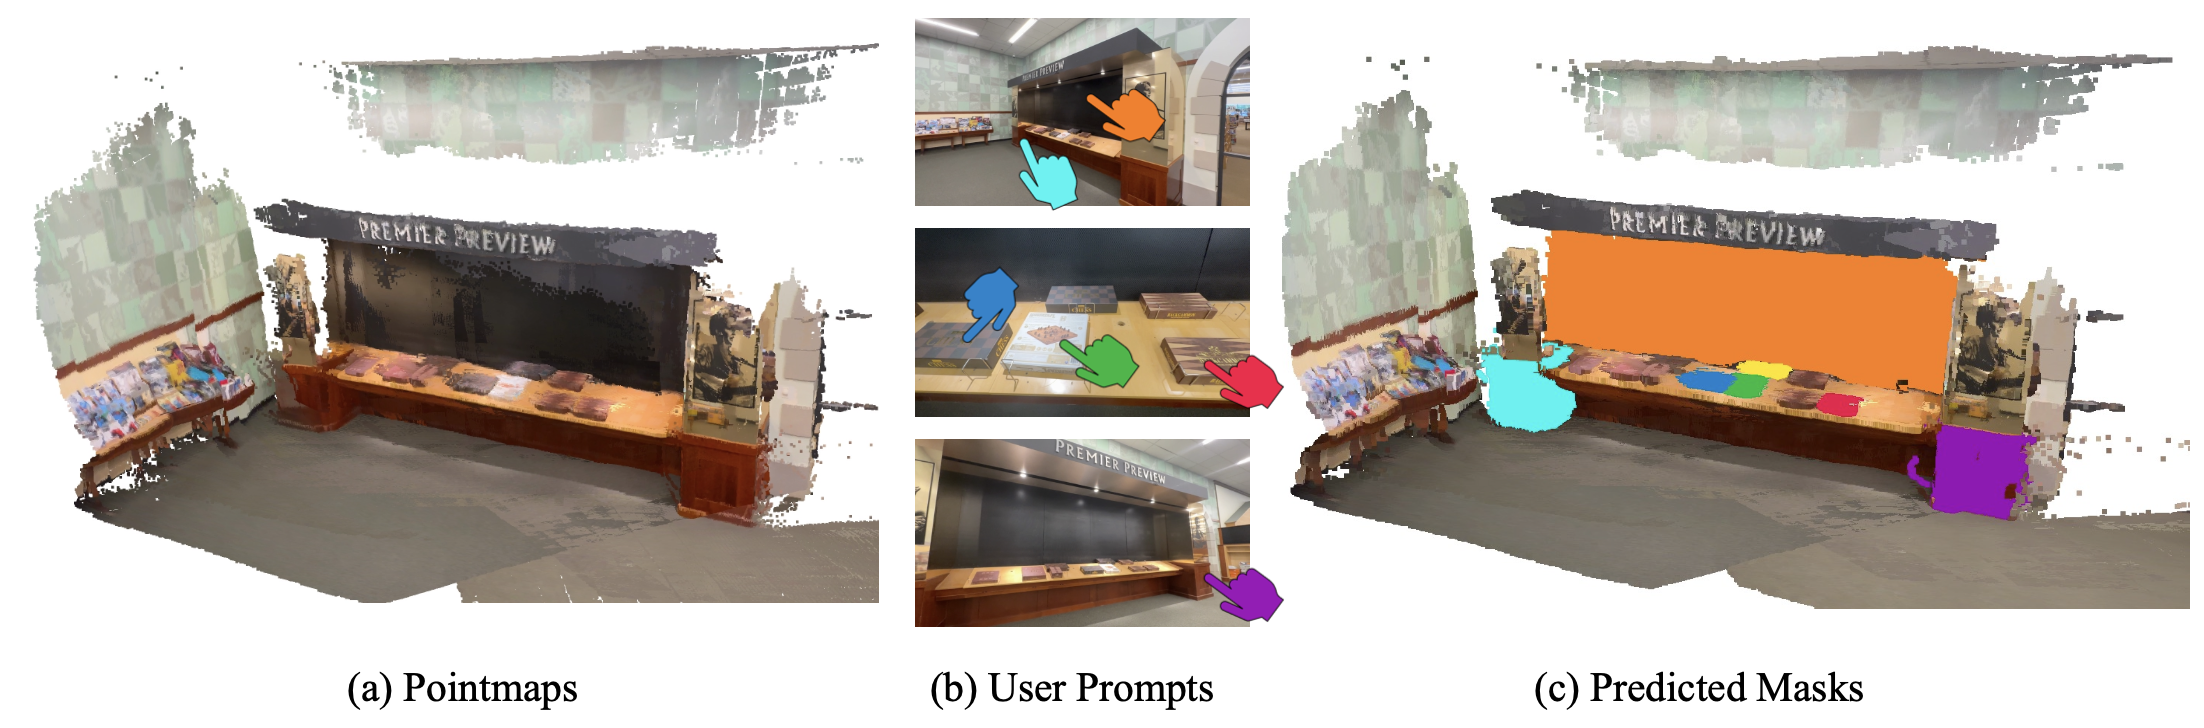
Click one object in one photo — get it segmented consistently in every view.
MV-SAM: Multi-view Promptable Segmentation using Pointmap Guidance
- Segmentation
- 3D Understanding
Problem
SAM-style segmenters lack 3D awareness, so masks drift between views of the same scene unless you run costly per-scene optimization.
Key idea
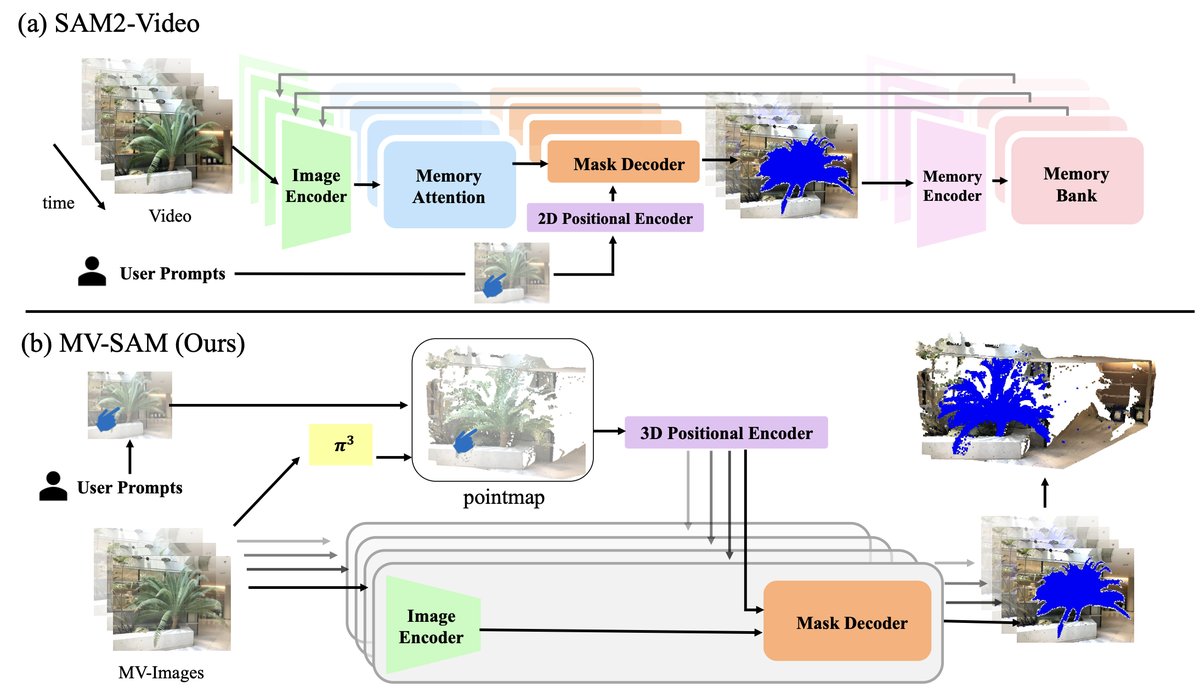
MV-SAM lifts SAM image embeddings and your prompts into 3D with pointmaps reconstructed from unposed images, so a transformer decodes masks that agree across views. No 3D network or 3D labels: it trains on SA-1B alone.
Result
Outperforms SAM2-Video and matches per-scene optimization baselines on NVOS, SPIn-NeRF, ScanNet++, uCo3D and DL3DV.
My role
First author: an extension of SAM to multi-view inputs, trained without 3D or video datasets.
BibTeX
@inproceedings{jeong2026mvsam,
  title = {MV-SAM: Multi-view Promptable Segmentation using Pointmap Guidance},
  author = {Jeong, Yoonwoo and Sun, Cheng and Wang, Yu-Chiang Frank and Cho, Minsu and Choe, Jaesung},
  booktitle = {NVIDIA tech report},
  year = {2026},
  eprint = {2601.17866},
  archiveprefix = {arXiv},
}
2025
-
3D Gaussian Splatting
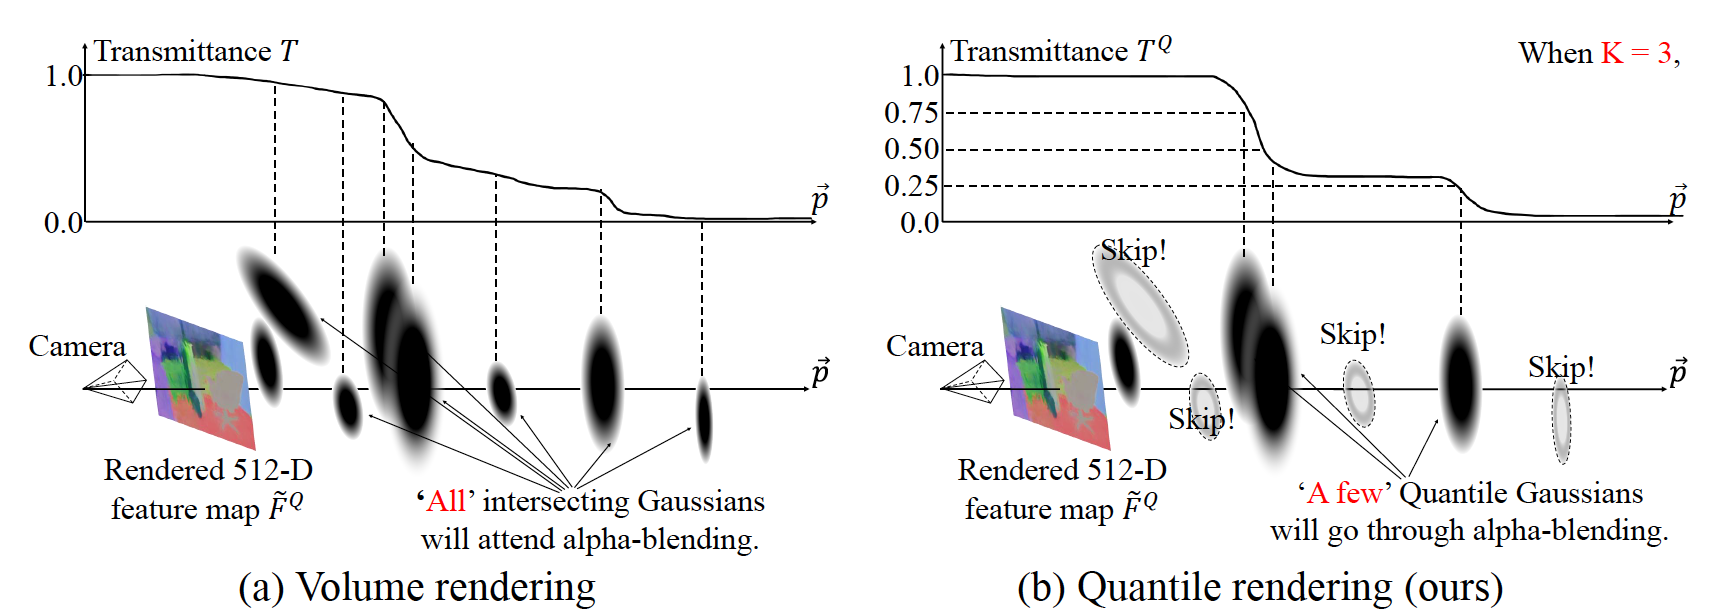
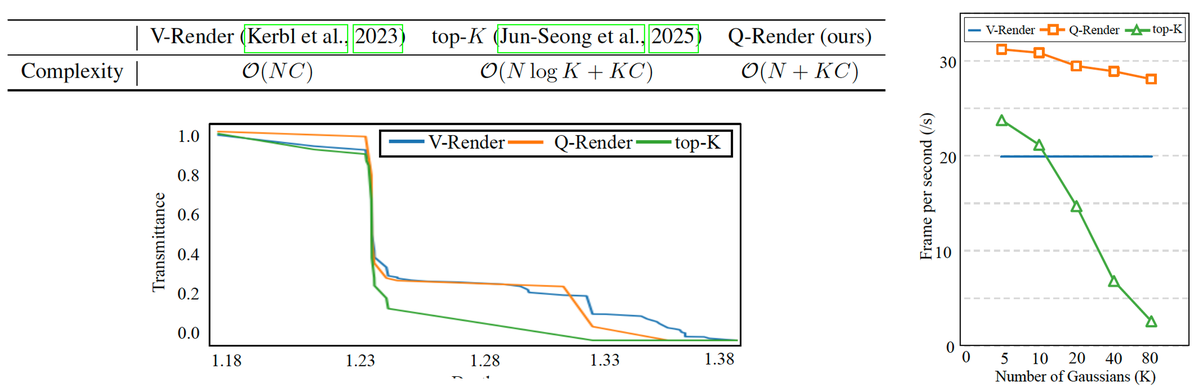
Render 512-D feature maps from 3D Gaussians ~44× faster by sampling only the Gaussians that matter.
Quantile Rendering: Efficiently Embedding High-dimensional Features on 3D Gaussian Splatting
- Gaussian Splatting
- Segmentation
- 3D Understanding
Problem
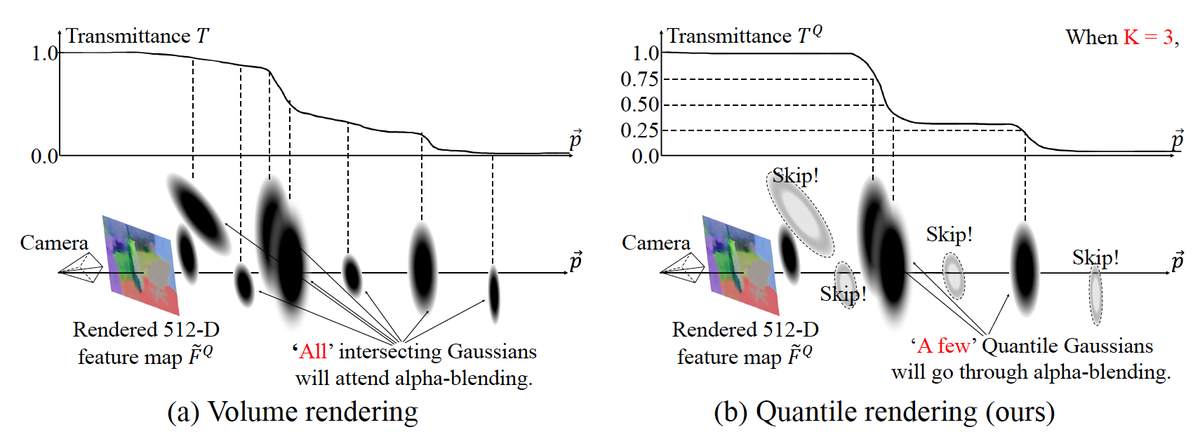
Attaching high-dimensional features such as CLIP embeddings to 3D Gaussians makes rendering slow, because every Gaussian along each ray is blended, so prior work compresses the features.
Key idea
Q-Render samples only the Gaussians with dominant influence along each ray, found by analyzing transmittance changes. A Gaussian Splatting Network (GS-Net) predicts the features, so it generalizes across scenes.
Result
43.7× faster 512-D feature rendering
State-of-the-art open-vocabulary 3D segmentation on ScanNet and LeRF-OVS, with real-time rendering of full 512-D features.
My role
First author: a generalizable 3D-GS network for open-vocabulary segmentation.
BibTeX
@inproceedings{jeong2025quantile, title = {Quantile Rendering: Efficiently Embedding High-dimensional Features on 3D Gaussian Splatting}, author = {Jeong, Yoonwoo and Sun, Cheng and Wang, Yu-Chiang Frank and Cho, Minsu and Choe, Jaesung}, booktitle = {NVIDIA tech report}, year = {2025}, eprint = {2512.20927}, archiveprefix = {arXiv}, } -
3D Gaussian Splatting
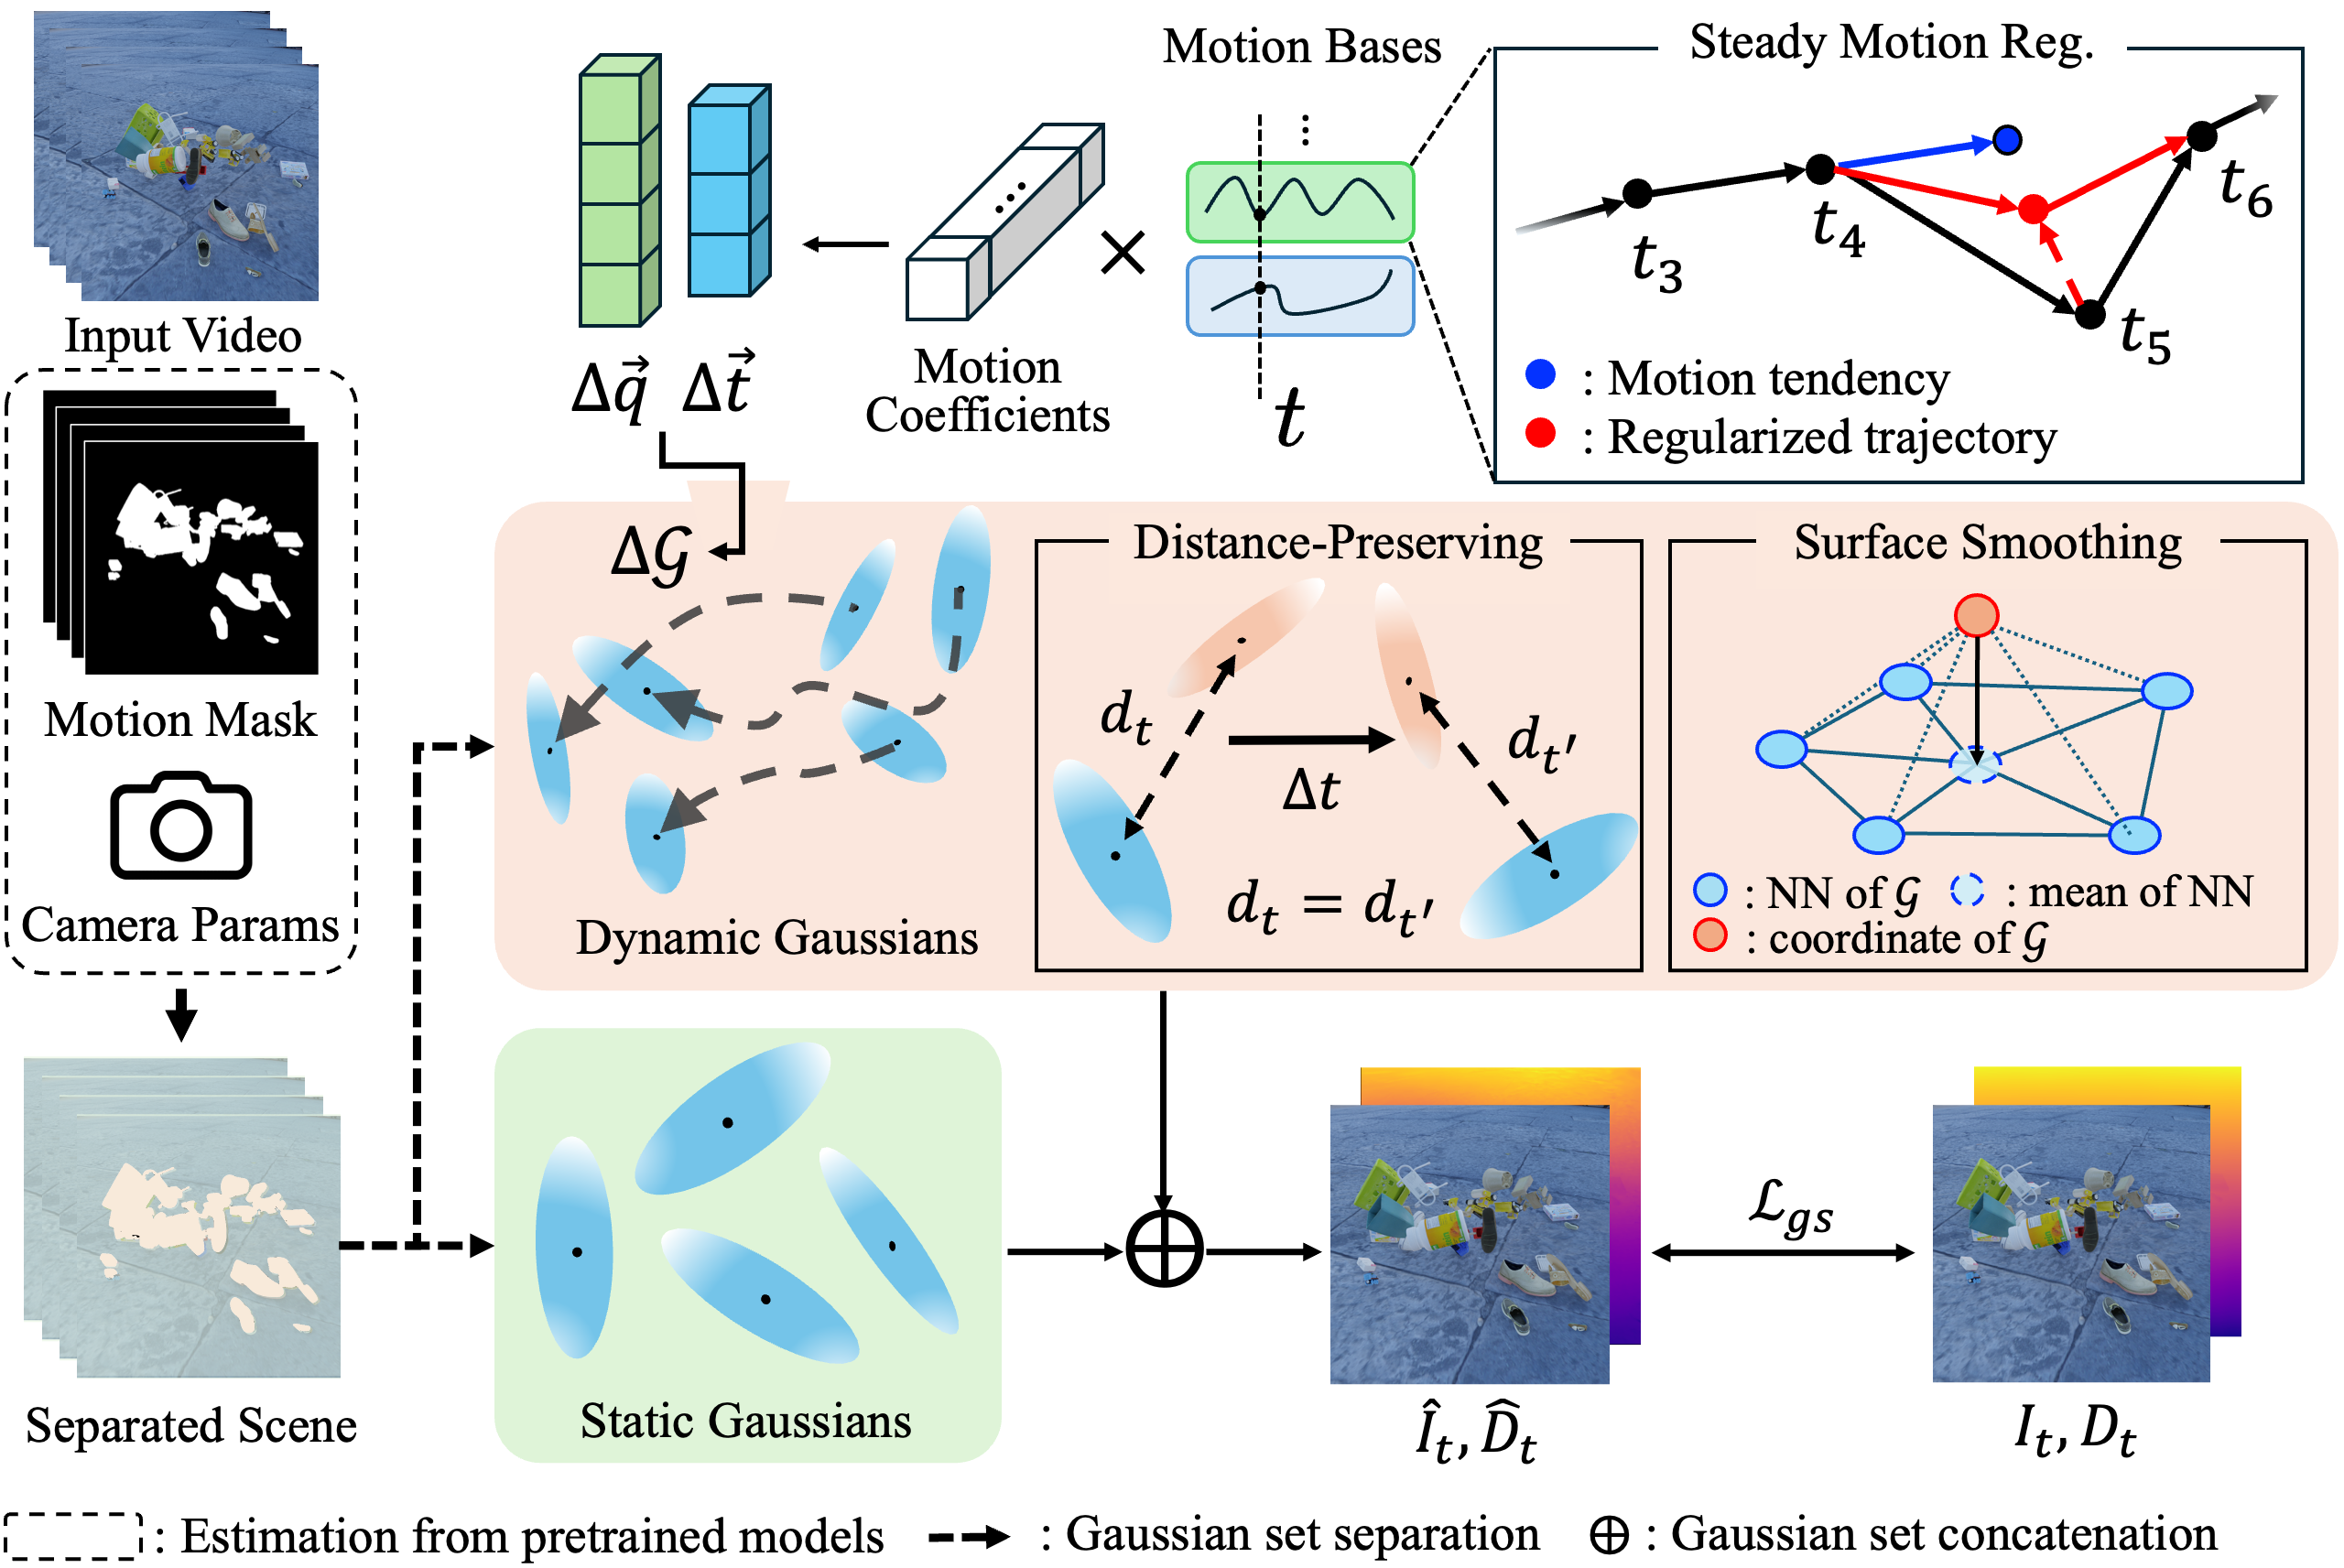
Rebuild moving scenes in 3D from a casual phone video — no camera poses needed.
RoDyGS: Robust Dynamic Gaussian Splatting for Casual Videos
* Equal contribution
- Gaussian Splatting
- Neural Fields
Problem
Casual videos come without camera poses or scene geometry, which makes optimizing dynamic 3D scenes from them fragile.
Key idea
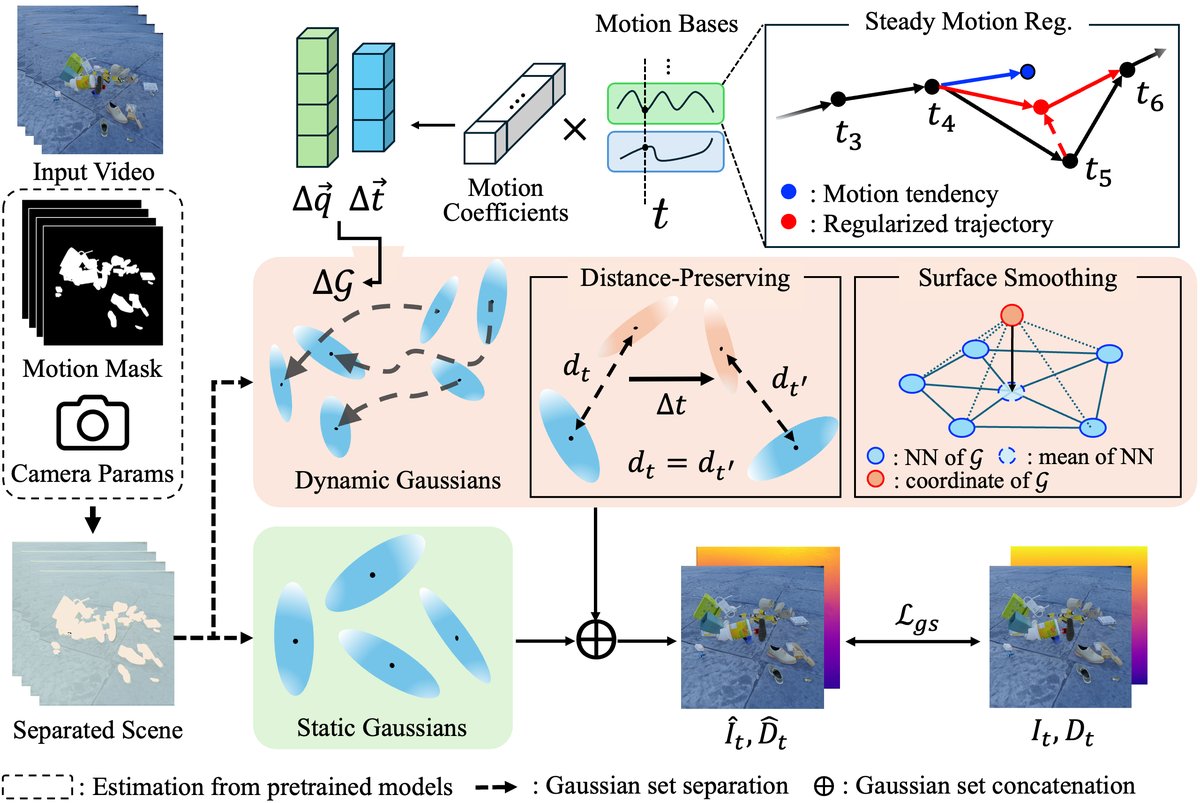
RoDyGS separates static and dynamic Gaussians and adds motion and geometry regularizers so the learned motion stays physically plausible. It also introduces Kubric-MRig, a benchmark with rich camera and object motion plus multi-view captures.
Result
Significantly outperforms previous pose-free dynamic neural fields and is competitive with pose-free static methods in rendering quality.
My role
Co-first author on this pose-free dynamic neural field pipeline that leverages geometric foundation models.
BibTeX
@inproceedings{jeong2024rodygs,
  title = {RoDyGS: Robust Dynamic Gaussian Splatting for Casual Videos},
  author = {Lee, Junmyeong and Choi, Hoseung and Jeong, Yoonwoo and Cho, Minsu},
  booktitle = {arXiv preprint},
  year = {2025},
  eprint = {2412.03077},
  archiveprefix = {arXiv},
}
2024
-

Multimodal LLMs & Generation
Turns a text-to-image model into a novel-view generator with a small plug-in, without full fine-tuning.
NVS-Adapter: Plug-and-Play Novel View Synthesis from a Single Image
* Equal contribution
- Generation
- Neural Fields
Problem
Novel view synthesis from one image usually fine-tunes a whole text-to-image model, which is expensive and erodes its ability to generate diverse images.
Key idea
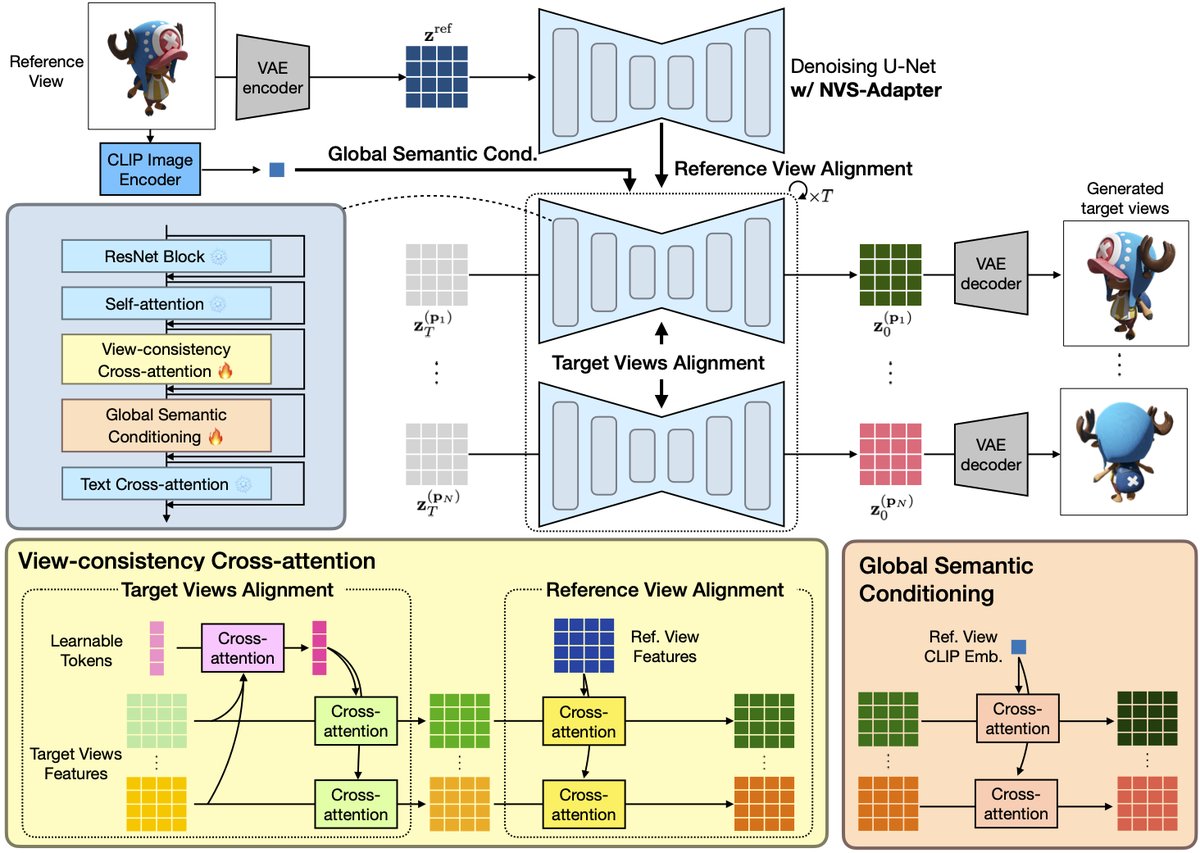
A plug-and-play adapter: view-consistency cross-attention aligns local details across views, and global semantic conditioning keeps generated views faithful to the reference image.
Result
Synthesizes geometrically consistent multi-views with strong benchmark results without full fine-tuning, and works with ControlNet and LoRA out of the box.
My role
First author (equal contribution): a parameter-efficient adapter for text-to-3D generative models.
BibTeX
@inproceedings{jeong2024nvsadapter,
  title = {NVS-Adapter: Plug-and-Play Novel View Synthesis from a Single Image},
  author = {Jeong, Yoonwoo and Lee, Jinwoo and Kim, Chiheon and Cho, Minsu and Lee, Doyup},
  booktitle = {European Conference on Computer Vision (ECCV)},
  year = {2024},
  eprint = {2312.07315},
  archiveprefix = {arXiv},
}
2023
-
Point Clouds & Canonicalization
Finds the upright, facing-forward pose of a 3D shape: stable for each object and consistent across a class.
Stable and Consistent Prediction of 3D Characteristic Orientation via Invariant Residual Learning
- Point Cloud
- Segmentation
Problem
Predicting a reliable characteristic orientation for 3D point clouds is hard: shapes of the same class can look very different, and predictions jump around under rotation.
Key idea
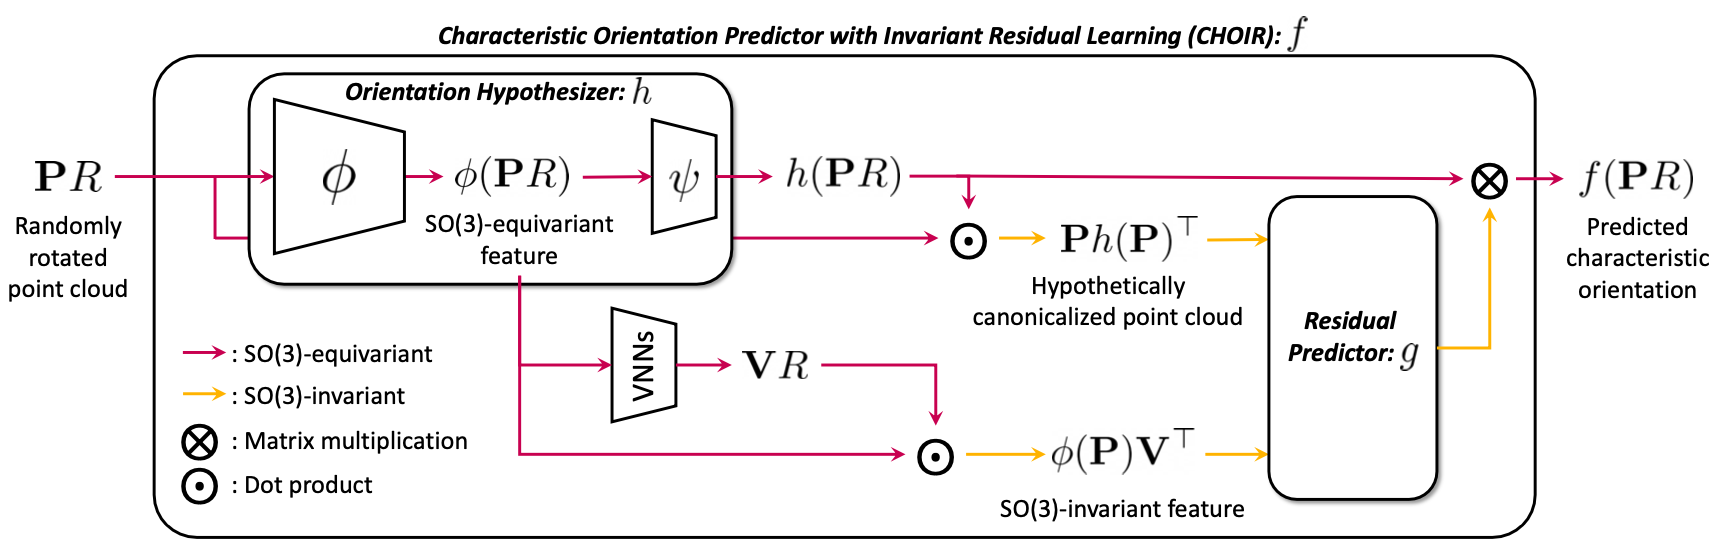
Decouple geometry and semantics: an SO(3)-equivariant network proposes an orientation from shape geometry, and an SO(3)-invariant residual rotation learned from semantics corrects it.
Result
Superior stability and consistency, and state-of-the-art part segmentation on randomly rotated point clouds.
My role
Third author: a 3D canonicalization framework for robust part-level segmentation.
BibTeX
@inproceedings{kim2023choir,
  title = {Stable and Consistent Prediction of 3D Characteristic Orientation via Invariant Residual Learning},
  author = {Kim, Seungwook and Park, Chunghyun and Jeong, Yoonwoo and Park, Jaesik and Cho, Minsu},
  booktitle = {International Conference on Machine Learning (ICML)},
  year = {2023},
  eprint = {2306.11406},
  archiveprefix = {arXiv},
}
2022
-

Point Clouds & Canonicalization
Teaches a network to find a point cloud’s canonical axis on its own, making 3D recognition robust to rotation.
SeLCA: Self-Supervised Learning of Canonical Axes
- Point Cloud
Problem
Point cloud features change dramatically when objects rotate, which hurts recognition.
Key idea
Self-supervised: predict a probabilistic canonical axis (rotation-equivariant), then align the point cloud to it, giving rotation-invariant input to any downstream network.
Result
Competitive ModelNet40 classification under unseen rotations, and high robustness to real-world corruptions in ModelNet40-C.
My role
Second author on this self-supervised canonicalization framework.
BibTeX
@inproceedings{kim2022selca, title = {SeLCA: Self-Supervised Learning of Canonical Axes}, author = {Kim, Seungwook and Jeong, Yoonwoo and Park, Chunghyun and Park, Jaesik and Cho, Minsu}, booktitle = {Conference on Neural Information Processing Systems Workshop (NeurIPS-W)}, year = {2022}, } -
Neural Fields & 3D Reconstruction
One clean PyTorch codebase for seven popular NeRF models and seven datasets.
NeRF-Factory: An awesome PyTorch NeRF collection
- Neural Fields
Problem
NeRF variants each shipped in their own codebase and framework, which made fair comparison and extension painful.
Key idea
Reimplement NeRF, NeRF++, DVGO, Plenoxels, Mip-NeRF, Mip-NeRF 360 and Ref-NeRF in a single extensible PyTorch library with shared data loaders and visualizers.
Result
1.3K GitHub stars (as of 2026)
An open-source library used by the NeRF community.
My role
Project leader: a PyTorch reimplementation of state-of-the-art NeRF models, released by Kakao Brain with Seungjoo Shin and Kibaek Park.
BibTeX
@misc{jeong2022nerffac, author = {Jeong, Yoonwoo and Shin, Seungjoo and Park, Kibaek}, title = {NeRF-Factory: An awesome PyTorch NeRF collection}, year = {2022}, url = {https://github.com/kakaobrain/nerf-factory}, note = {Version 1.0}, howpublished = {\url{https://github.com/kakaobrain/nerf-factory}}, } -
Neural Fields & 3D Reconstruction
The first large-scale datasets of neural radiance fields, so perception models can learn directly from NeRFs.
PeRFception: Perception using Radiance Fields
* Equal contribution
- Neural Fields
- 3D Understanding
Problem
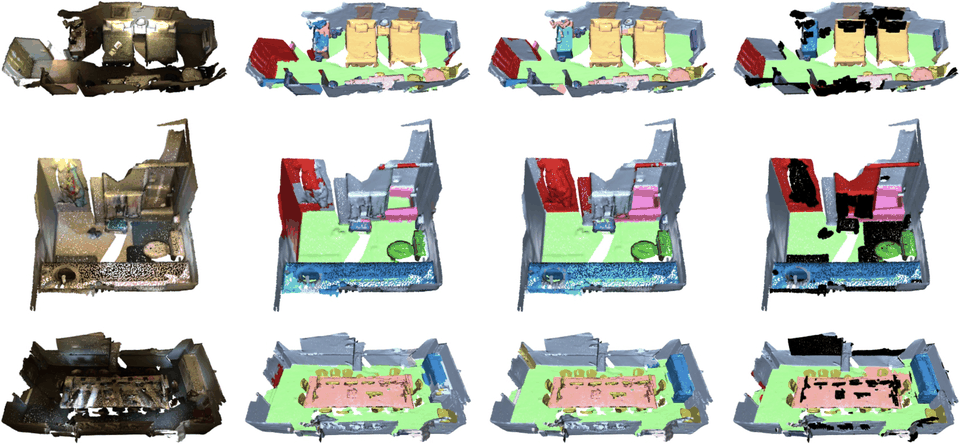
A NeRF packs hundreds of images into one compact 3D representation, but there were no large-scale NeRF datasets for training perception models.
Key idea
Convert object-centric and scene-centric scans into Plenoxels, then build classification and segmentation models that take this implicit format as input, with an augmentation that stops them overfitting to backgrounds.
Result
96.4% memory compression vs. the original dataset
Compresses the source datasets by 96.4% while keeping both 2D and 3D information in one unified format.
My role
First author (equal contribution) of this large-scale neural field dataset for perception tasks; I also led the open-source project.
BibTeX
@inproceedings{jeong2022perf, title = {PeRFception: Perception using Radiance Fields}, author = {Jeong, Yoonwoo and Shin, Seungjoo and Lee, Junha and Choy, Christopher and Anandkumar, Animashree and Cho, Minsu and Park, Jaesik}, booktitle = {Conference on Neural Information Processing Systems Dataset and Benchmark (NeurIPS-D)}, year = {2022}, eprint = {2208.11537}, archiveprefix = {arXiv}, } -

3D Understanding & Segmentation
A point cloud transformer that runs 129× faster than Point Transformer on large 3D scenes.
Fast Point Transformer
- Point Cloud
- Segmentation
- 3D Understanding
Problem
Large 3D scenes are usually chopped into small regions and stitched back together, adding pre- and post-processing and losing global context.
Key idea
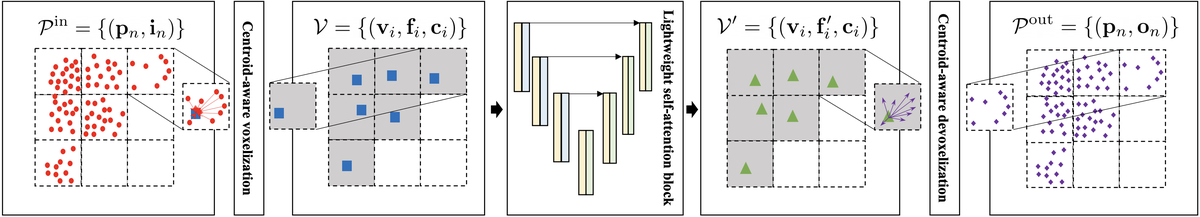
A lightweight self-attention layer that encodes continuous 3D coordinates, on top of a voxel-hashing architecture, so whole scenes are processed efficiently.
Result
129× faster inference than Point Transformer (S3DIS)
Accuracy competitive with the best voxel-based methods on 3D semantic segmentation and detection, with 129× faster inference than Point Transformer on S3DIS.
My role
Second author: an efficient voxel-based architecture for 3D perception.
BibTeX
@inproceedings{park2022fpt,
  title = {Fast Point Transformer},
  author = {Park, Chunghyun and Jeong, Yoonwoo and Cho, Minsu and Park, Jaesik},
  booktitle = {{IEEE/CVF} Conference on Computer Vision and Pattern Recognition (CVPR)},
  year = {2022},
  eprint = {2112.04702},
  archiveprefix = {arXiv},
}
2021
-
Matching & Local Features
Learns how large and which way up an image patch is, without a single pose label.
Self-supervised Learning of Image Scale and Orientation Estimation
- Matching
Problem
Assigning a characteristic scale and orientation to an image region sounds simple, but large sets of patches with pose labels do not exist.
Key idea
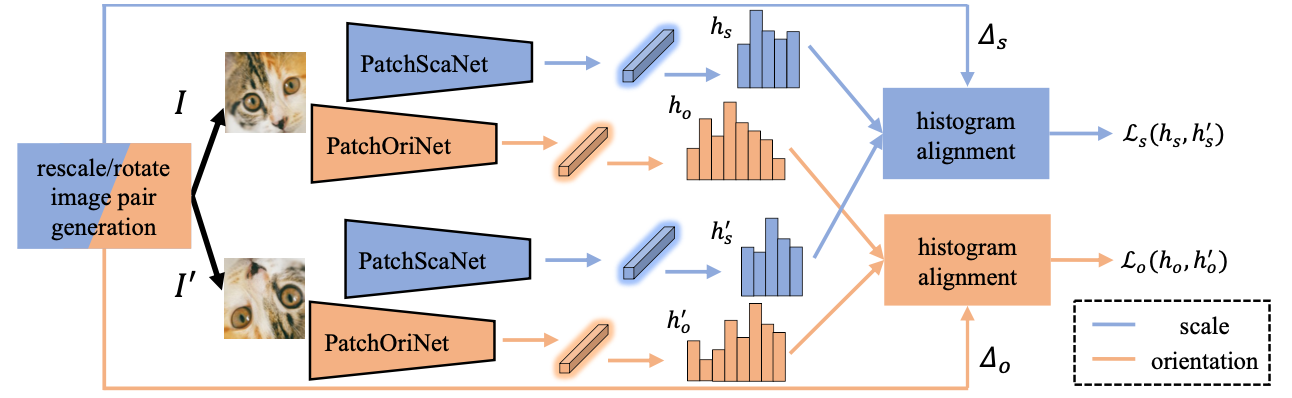
Randomly rescale and rotate patches, then train an estimator to predict scale and orientation histograms whose differences match the applied transform: a histogram alignment trick that needs no labels.
Result
Significantly outperforms previous scale and orientation estimators, and improves image matching and 6-DoF camera pose estimation.
My role
Second author: a self-supervised framework for image canonicalization and matching.
BibTeX
@inproceedings{lee2022sslso, title = {Self-supervised Learning of Image Scale and Orientation Estimation}, author = {Lee, Jongmin and Jeong, Yoonwoo and Cho, Minsu}, booktitle = {British Machine Vision Conference (BMVC)}, year = {2021}, eprint = {2206.07259}, archiveprefix = {arXiv}, } -
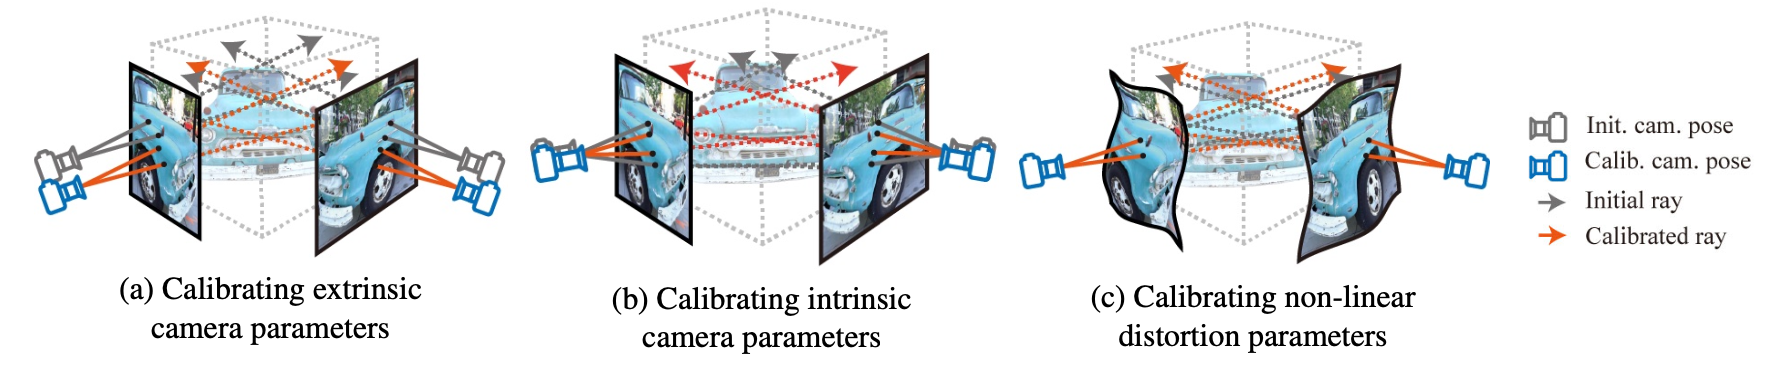
Neural Fields & 3D Reconstruction
Learn a NeRF and the camera itself — lens distortion included — without COLMAP.
Self-calibrating Neural Radiance Fields
- Neural Fields
Problem
NeRF needs accurate camera poses and intrinsics, usually from COLMAP, and real lenses add non-linear distortions that simple camera models miss.
Key idea
Jointly learn the scene and a generic camera model (pinhole, fourth-order radial distortion and a learnable noise model) using photometric consistency plus a new projected ray distance loss.
Result
Learns intrinsics and poses from scratch without COLMAP initialization and improves PSNR over baselines; it plugs into other NeRF variants.
My role
First author of the first pose-free NeRF optimization pipeline; I also led the open-source project.
BibTeX
@article{jeong2022scnerf, title = {Self-calibrating Neural Radiance Fields}, author = {Jeong, Yoonwoo and Ahn, Seokjun and Choy, Christopher and Anandkumar, Animashree and Cho, Minsu and Park, Jaesik}, journal = {{IEEE/CVF} Conference on International Conference on Computer Vision (ICCV)}, year = {2021}, eprint = {2108.13826}, archiveprefix = {arXiv}, } -

Matching & Local Features
Squeezes CNN features into local descriptors up to 100× smaller that still match well.
Learning to Distill Convolutional Features into Compact Local Descriptors
- Matching
Problem
Local descriptor research focused on accuracy, not size, yet large descriptors are costly to store and match.
Key idea
Distill several intermediate CNN features, from local textures to non-local semantics, into a compact descriptor of any chosen dimension.
Result
100× smaller descriptors
Significantly better semantic correspondence than existing models with up to 100× smaller descriptors, and it generalizes to wide-baseline matching and visual localization.
My role
Second author: a memory-efficient feature extractor for geometric matching.
BibTeX
@inproceedings{lee2021learning,
  title = {Learning to Distill Convolutional Features into Compact Local Descriptors},
  author = {Lee, Jongmin and Jeong, Yoonwoo and Kim, Seungwook and Min, Juhong and Cho, Minsu},
  booktitle = {IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)},
  year = {2021},
}